Repository Details
Shared by
HelloGitHub Rating
9.2
9 ratings
DeepSeek's Open-Source MoE Model
Past 6 days Received 53 stars ✨
Use arrow keys to explore dates, Home and End for the first and last date, Escape to dismiss.| Date | Star | Daily change |
|---|---|---|
| 周日 | 104,769 | — |
| 周一 | 104,784 | +15 |
| 周二 | 104,794 | +10 |
| 周三 | 104,801 | +7 |
| 周四 | 104,816 | +15 |
| 周五 | 104,822 | +6 |
104.8k
Stars
Yes
Chinese
Python
Language
No
Active
26
Contributors
333
Issues
Yes
Organization
None
Latest
2w
Forks
MIT
License
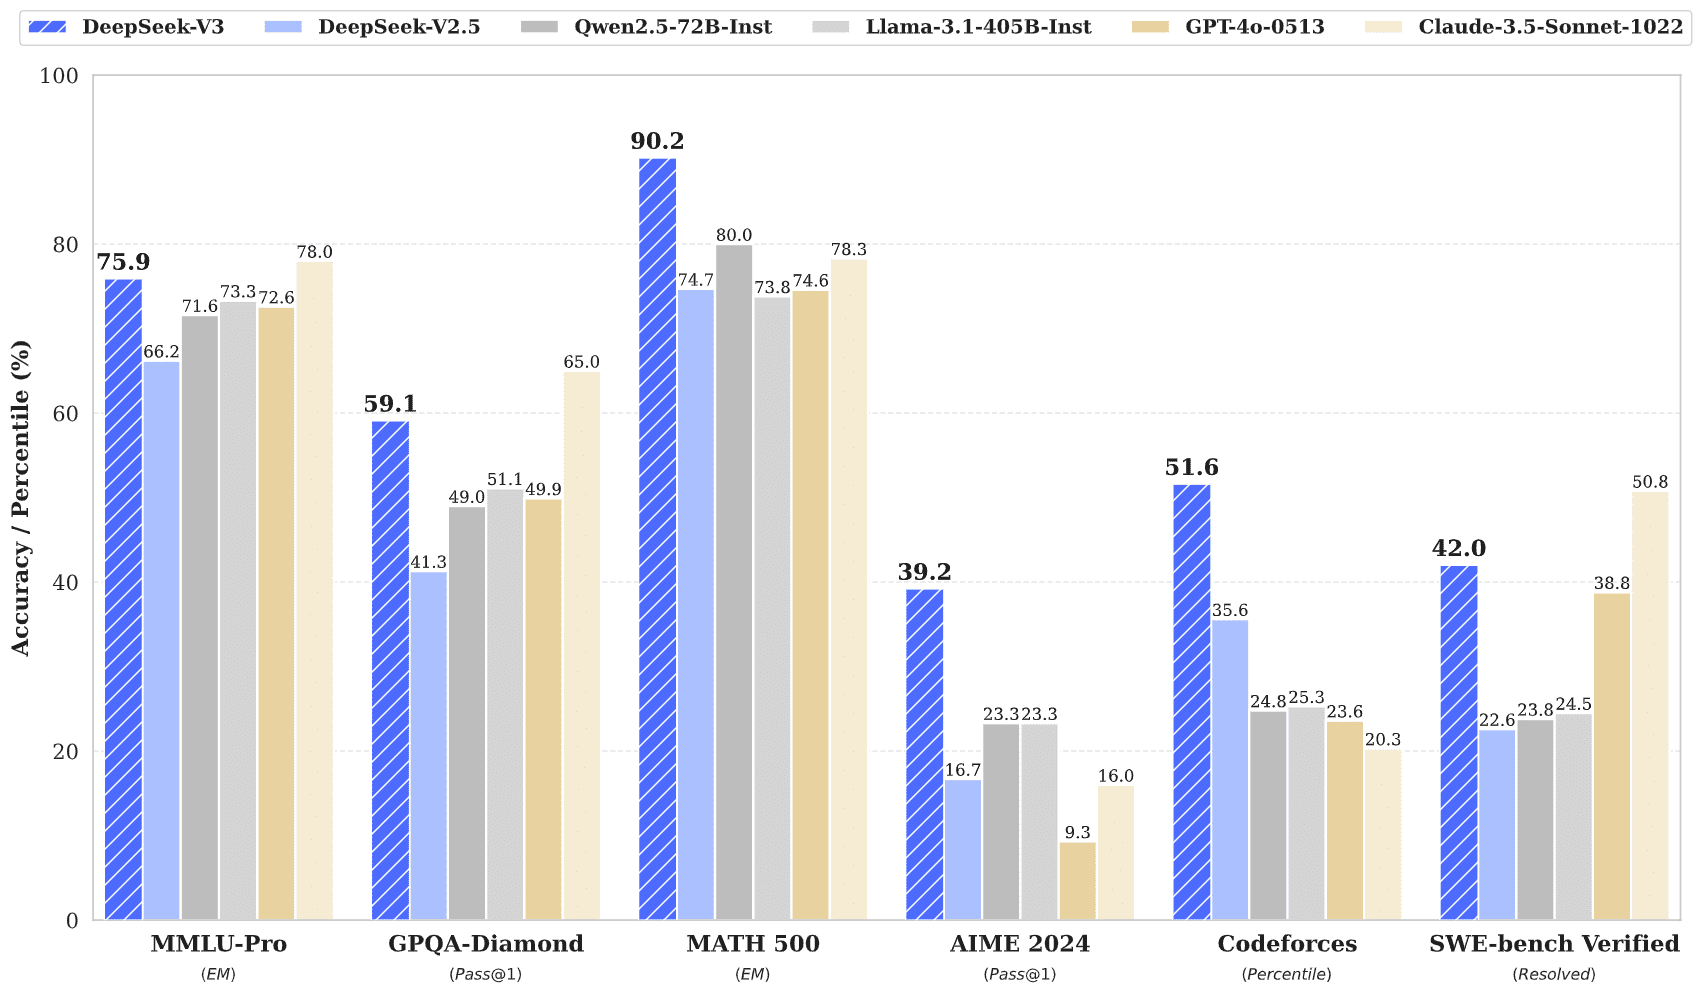
This is an open-source large language model based on the Mixture of Experts (MoE) and Multi-Head Latent Attention (MLA) architectures, which performs exceptionally well in complex tasks such as mathematical reasoning and code generation. The model has a total scale of 671B parameters, but only 37B parameters are activated for each token. That is, not all 'experts' participate in the computation when processing inputs; instead, a subset of experts is selected for processing. By activating only a portion of the parameters (37B), the model can complete computations, significantly reducing the costs of training and inference.
Comments

Rating:
No comments yet