Repository Details
Shared by
HelloGitHub Rating
10.0
1 ratings
An Open Source Speech Synthesis Model for Everyone
Past 6 days Received 89 stars ✨
Use arrow keys to explore dates, Home and End for the first and last date, Escape to dismiss.| Date | Star | Daily change |
|---|---|---|
| 周日 | 33,626 | — |
| 周一 | 33,642 | +16 |
| 周二 | 33,665 | +23 |
| 周三 | 33,687 | +22 |
| 周四 | 33,700 | +13 |
| 周五 | 33,715 | +15 |
33.7k
Stars
Yes
Chinese
Python
Language
Yes
Active
104
Contributors
25
Issues
Yes
Organization
None
Latest
3k
Forks
None
License
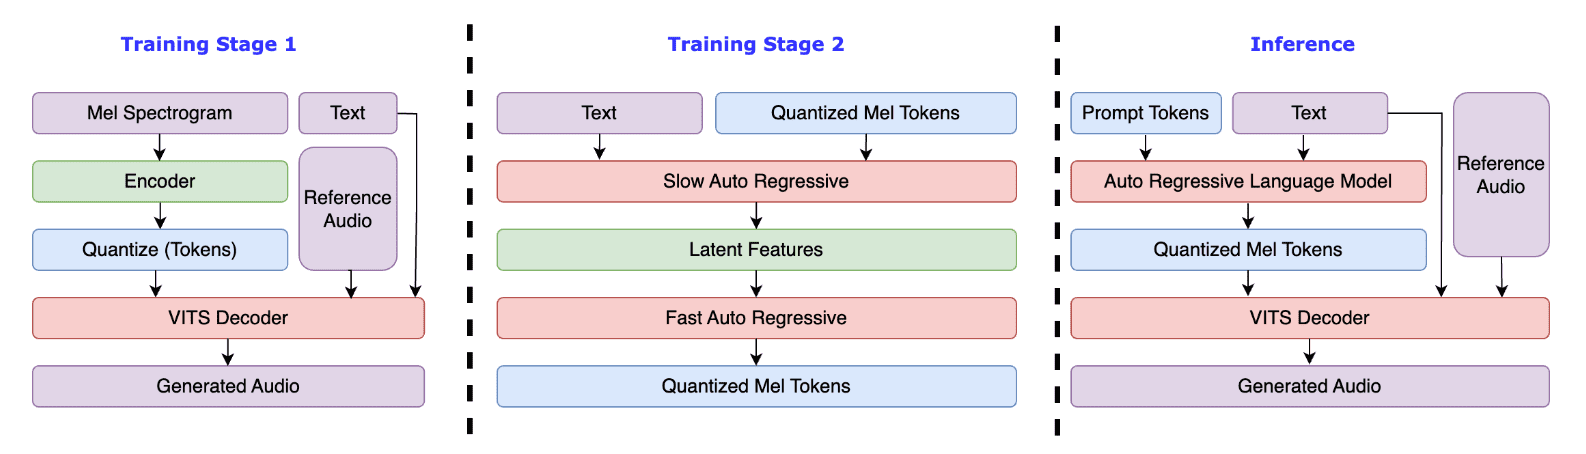
This project is a text-to-speech model developed by Fish Audio, based on VQGAN+Llama technology. It can be easily run and fine-tuned on personal devices with only 4GB of video memory (16GB recommended), supports Chinese, English, and Japanese languages, and allows voice timbre adjustments, delivering excellent speech synthesis quality.
Comments

Rating:
No comments yet