Repository Details
Shared by
HelloGitHub Rating
10.0
1 ratings
Python Library for Easily Extracting PDF Text and Tables
Past 6 days Received 9 stars ✨
Use arrow keys to explore dates, Home and End for the first and last date, Escape to dismiss.| Date | Star | Daily change |
|---|---|---|
| 周日 | 10,886 | — |
| 周一 | 10,886 | 0 |
| 周二 | 10,890 | +4 |
| 周三 | 10,895 | +5 |
| 周四 | 10,894 | -1 |
| 周五 | 10,895 | +1 |
10.9k
Stars
Yes
Chinese
Python
Language
Yes
Active
42
Contributors
139
Issues
No
Organization
None
Latest
951
Forks
MIT
License
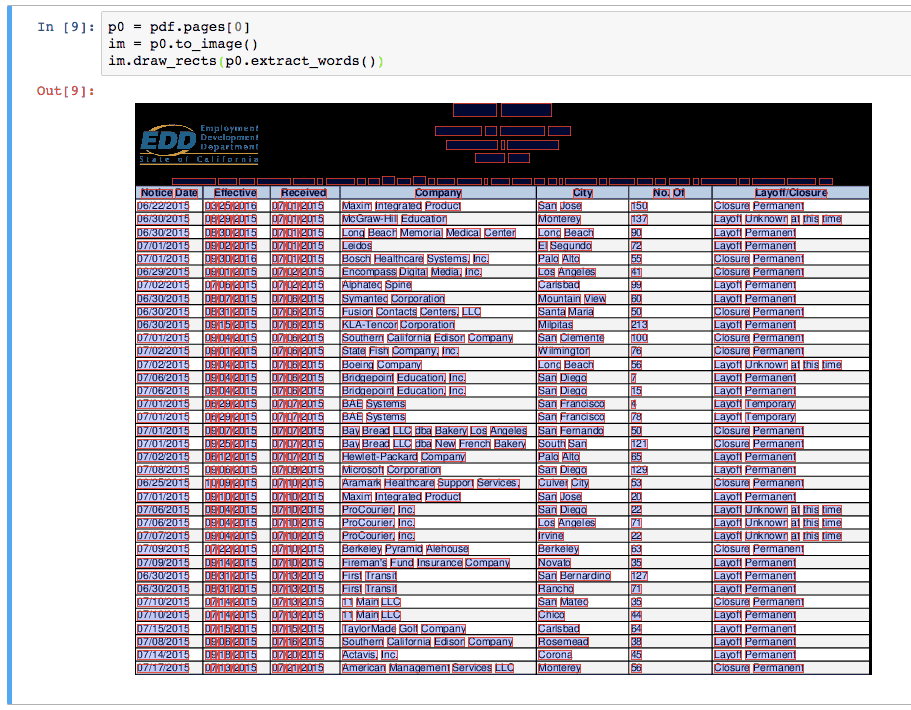
This project is a Python-based PDF parsing and data extraction library that can easily extract text and tables. It is able to accurately obtain detailed positions, sizes and font information of each character, line, rectangle and other elements in the PDF document, and supports one-click generation of page snapshots for convenient debugging.
Comments

Rating:
No comments yet