Repository Details
Shared by
HelloGitHub Rating
10.0
4 ratings
Running 70B Large Models with Just 4GB VRAM
Past 6 days Received 337 stars ✨
Use arrow keys to explore dates, Home and End for the first and last date, Escape to dismiss.| Date | Star | Daily change |
|---|---|---|
| 周二 | 42,125 | — |
| 周三 | 42,196 | +71 |
| 周四 | 42,257 | +61 |
| 周五 | 42,325 | +68 |
| 周六 | 42,389 | +64 |
| 周日 | 42,462 | +73 |
42.5k
Stars
No
Chinese
Jupyter Notebook
Language
Yes
Active
18
Contributors
157
Issues
No
Organization
None
Latest
4k
Forks
Apache-2.0
License
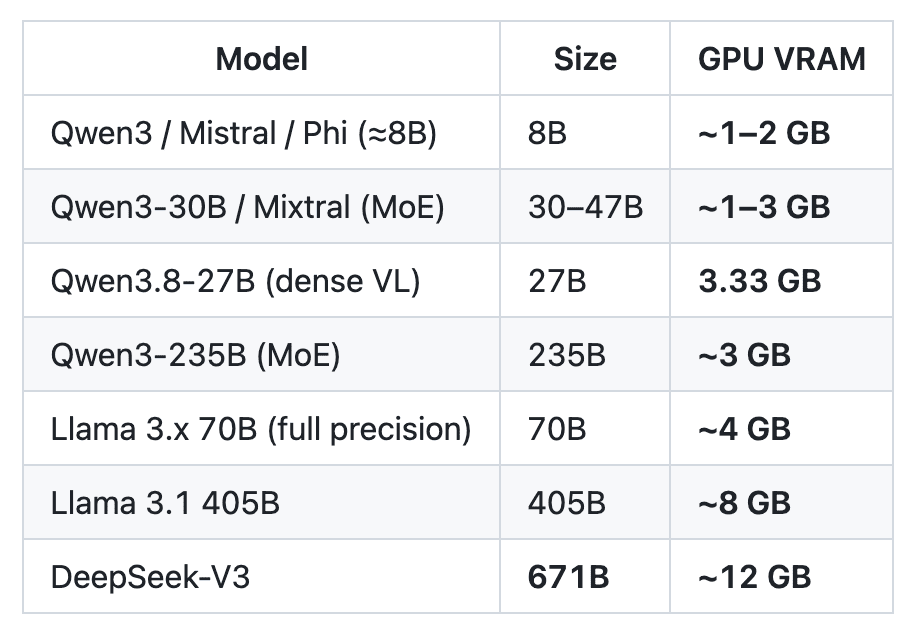
This is a Python library that drastically reduces inference VRAM usage via hierarchical loading. It can run 70B large models with only 4GB VRAM without quantization, distillation, or pruning. It supports mainstream models such as Llama 3.x, Qwen3, DeepSeek, and offers prefetch acceleration, 8bit/4bit quantization, and macOS support.
Comments

Rating:
No comments yet