Repository Details
Shared by
HelloGitHub Rating
0 ratings
More Efficient LLMs Inference and Service Engine
Past 6 days Received 314 stars ✨
Use arrow keys to explore dates, Home and End for the first and last date, Escape to dismiss.| Date | Star | Daily change |
|---|---|---|
| 周日 | 96,558 | — |
| 周一 | 96,622 | +64 |
| 周二 | 96,689 | +67 |
| 周三 | 96,770 | +81 |
| 周四 | 96,834 | +64 |
| 周五 | 96,872 | +38 |
96.9k
Stars
No
Chinese
Python
Language
Yes
Active
4k
Contributors
1w
Issues
Yes
Organization
None
Latest
2w
Forks
Apache-2.0
License
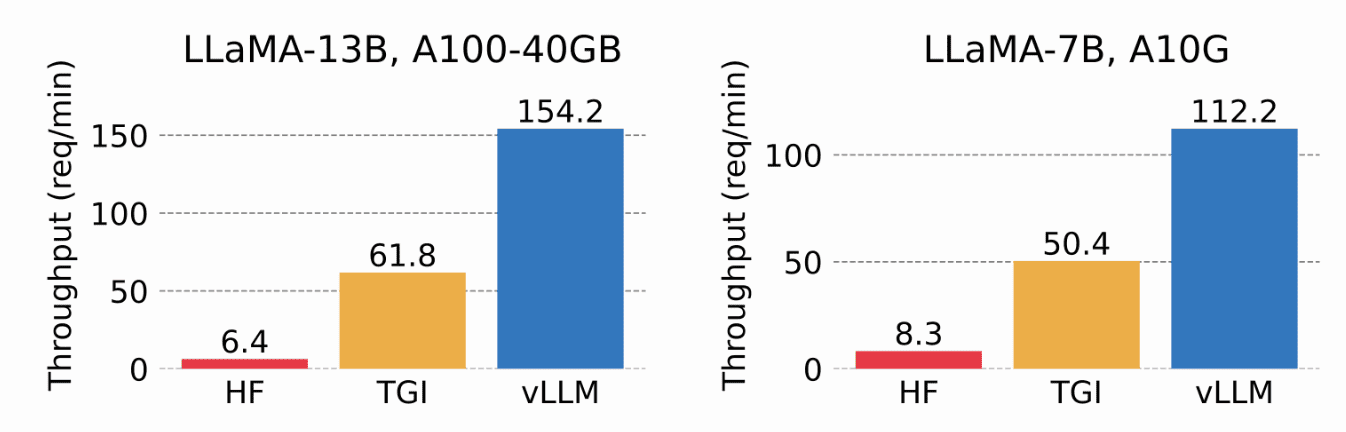
This is a highly efficient and user-friendly large language model inference engine, specifically designed to address issues such as slow inference speeds and low resource utilization. It is based on PyTorch and CUDA, and incorporates memory optimization algorithms (PagedAttention), computational graph optimization, and model parallelization techniques to significantly reduce GPU memory usage and fully leverage multi-GPU resources to enhance inference performance. At the same time, vLLM is seamlessly compatible with HF models. It supports efficient operation on a variety of hardware platforms such as GPUs, CPUs, and TPUs, suitable for real-time question answering, text generation, and recommendation systems.
Comments

Rating:
No comments yet